Maniformer Presents MEgoVista, a Metric-Scale 4D Hand and Head Motion Reconstruction System
Researchers from both Northwestern Polytechnical University and Xi’an Jiaotong University have developed MEgoVista. This is an offline system that takes the egocentric video from the MEgo View and produces metric-scale 4D motion data for both hands and the head.
Paper: https://arxiv.org/abs/2609.16684
Ego (Ego-centric) video enables researchers to gather data in real-world settings rather than just in the confines of a lab, making it a very useful source of data for embodied AI pretraining. The problem is that simply recording the activity doesn’t give you the motion data that you need to train the models. You still need to be able to identify the user’s hands, track the movement of the fingers, and measure the distance the hands move in real-world units.
Why Is Measuring Egocentric Motion Accurately So Hard?
To use Ego video for model training, you need the human action to be accurately translated into robot action. There are still a number of challenges to go from collecting the video through to motion reconstruction.
Current methods are all a compromise. Multi-camera studio systems are accurate but require specialist equipment and are only viable in the studio. Real-world video datasets have a huge range of scenes but lack metric-scale 3D hand annotations, so they can’t give you actual hand positions or hand movement distances.
Single camera methods have another problem in that they are estimating distance from learned patterns rather than actually measuring it. The hand may look correct in the image but be in the wrong 3D position. Real-world activities are a further complication. During a manicure, for instance, you can have both the subject’s hand and a passer-by’s hand in the frame, and you need to be able to tell them apart. Fingers can be occluded by tools or arms, and head turns will move the camera, so hand motion has to be separated from camera motion.
Three Steps to Reconstruction: Identify the Hands, Measure Distance, Refine Motion
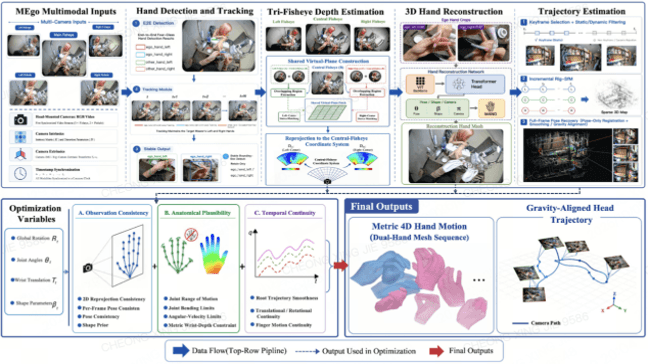
MEgoVista uses an offline reconstruction pipeline built on three steps:
- Identify the wearer’s hands.MEgoVista detects hands, can tell left from right and can work out which hands belong to the wearer. That way it doesn’t get confused between a passerby’s hands and the wearer’s hands if they happen to be touching.
- Measure distance with multiple cameras. The MEgo View headset has three fisheye cameras recording at 60fps. The central camera is paired with each of the side cameras to create two stereo pairs. Pre-calibrated baselines are used to align the images; depth is estimated via FoundationStereo, and the results are combined, with the most reliable estimates being selected.
- Refine the full sequence. Rather than trusting each frame in isolation, MEgoVista filters for reliable observations and optimizes the whole sequence, producing smoother motion and finger poses that respect human anatomy.
For the head the system reconstructs its path using images from the multiple cameras, sets the metric scale at the outset and uses the inertial data to determine the vertical. Both hands and head are in a single metric scale 4D coordinate system.
Evaluation Results: Higher Accuracy and More Reliable Hand Identification
The team tested MEgoVista against reference data from a separate optical motion capture system (26 cameras). They also kept a count of the number of hand detections that were missed so the various methods couldn’t simply improve their scores by simply dropping the really hard frames.
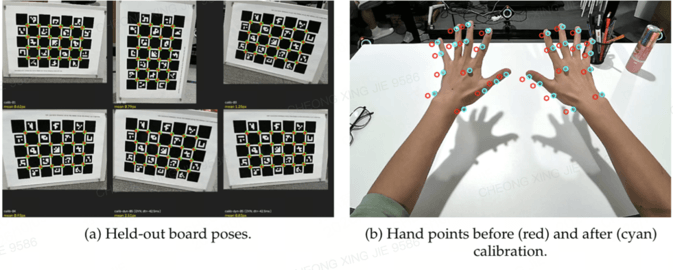
Verifying Alignment Between Motion-Capture Data and Camera Footage
MEgoVista’s finger pose error (PA-MPJPE-p) was 4.29mm versus 16.30mm for HaWoR and 49.18mm for Dyn-HaMR. Its absolute wrist position error in the camera frame (CT-p) was 14.30mm as opposed to 46.70mm for HaWoR and 184.38mm for Dyn-HaMR.
In the test set MEgoVista produced zero missed or false hand detections and also had lower motion jitter than both of the baseline methods (1.11mm/frame²). In the two head trajectory tests the average position error over the full sequence was 2.87mm and 0.75mm respectively, compared to 3.27mm and 1.00mm for the offline refined ORB-SLAM3 baseline.
The team also conducted further comparisons in three real-world scenarios:
- Milk tea preparation: When both hands were moving, the reconstructed skeletons of MEgoVista and Dyn-HaMR were quickly and very closely aligned with the hands; HaWoR, on the other hand, showed a very obvious misalignment in the left hand skeleton.
- Manicure: Both HaWoR and Dyn-HaMR at various times misattributed a bystander’s hand to the wearer when the two hands came into contact. MEgoVista correctly identified the two individuals.
- Animal washing: When the hands were soiled and in motion, both MEgoVista and Dyn-HaMR picked up the hands, whereas HaWoR showed displacement in the left hand and wrist.
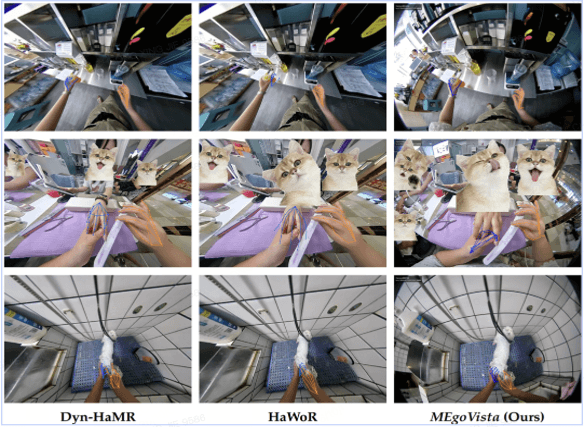
Visual comparisons demonstrate that MEgoVista is far more consistent at detecting hands in dynamic situations and when multiple people are present. It reconstructs skeletal motion in a way that more accurately reflects the actual position of the hands and is much better at distinguishing the wearer’s hands from those of others.
MEgoVista takes the human actions captured in Ego videos and turns them into metric-scale 4D motion, which it then validates against independent reference data. This provides a much more reliable source of data for robot learning.
About Maniformer
Maniformer is a premier Physical AI data platform that provides the data infrastructure for embodied intelligence. It’s a complete platform that brings together intelligent data collection hardware, a powerful data engine, and end-to-end data services to turn real-world physical interactions into high-quality, scalable data. It covers the full lifecycle from collection and processing through to validation and intelligent operations, providing a robust data foundation for faster development and deployment of Physical AI.
Find out more about Maniformer here: https://maniformer.ai/en
Popular on OTW Right Now!
About The Author

Gagan Bhangu
Founder of otechworld.com and managing editor. He is a tech geek, web-developer, and blogger. He holds a master's degree in computer applications and making money online since 2015.